AIPOCH Open-Science answered 36 of 37 scored tasks correctly in a local evaluation on AstaBench’s CORE-Bench-Hard test split: 97.30% task accuracy. Every task received a score, with one marked incorrect. The final per-task tally includes retests.
What CORE-Bench-Hard tests
Ai2 describes CORE-Bench-Hard as an evaluation of computational reproducibility. In the hard setting, an agent is given code and data associated with a published study and a README, without step-by-step reproduction instructions or a Dockerfile. It must install the requirements, run the necessary analysis, and obtain the requested results.
The AstaBench v0.5.4 implementation instructs the agent to put its answers in report.json and uses a programmatic task scorer. The questions can request numbers, text, or lists. A task with multiple answer fields receives its one point only when every required answer is correct; a partially correct task does not receive a fraction of a point.
That scoring rule matters when reading the result. 36/37 counts fully correct tasks, not 36 correct fields or an average of partially correct answers.
The reported result and evaluation setup
AIPOCH’s evaluation report gives the following result for the official test split:
| Measure | Reported result |
|---|---|
| Total test tasks | 37 |
| Tasks that received a score | 37 |
| Fully correct tasks | 36 |
| Incorrect tasks | 1 |
| Task accuracy | 97.30% (36/37) |
The report describes this configuration:
| Component | Reported configuration |
|---|---|
| Agent | AIPOCH Open-Science |
| Main model | DeepSeek Flash (deepseek-flash) |
| Reasoning setting | Max |
| Host and execution environment | Windows host, WSL Ubuntu 24.04, Docker, and Inspect |
| Execution tool | Official python_session |
| Scoring | Official programmatic task scorer, run locally; each task receives 0 or 1 point |
The report also notes that an image from the original sandbox could be passed into AIPOCH Open-Science for inspection. This describes an available part of the reported evaluation workflow; it is not evidence that every task required image inspection.
The 36/37 figure is the report’s final task-by-task tally including retests. It should not be read as the outcome of a single uninterrupted first attempt. The report does not specify which tasks were retested, how many attempts were made, or how a final attempt was selected. This tally is therefore not necessarily comparable with records produced under a single-submission protocol.
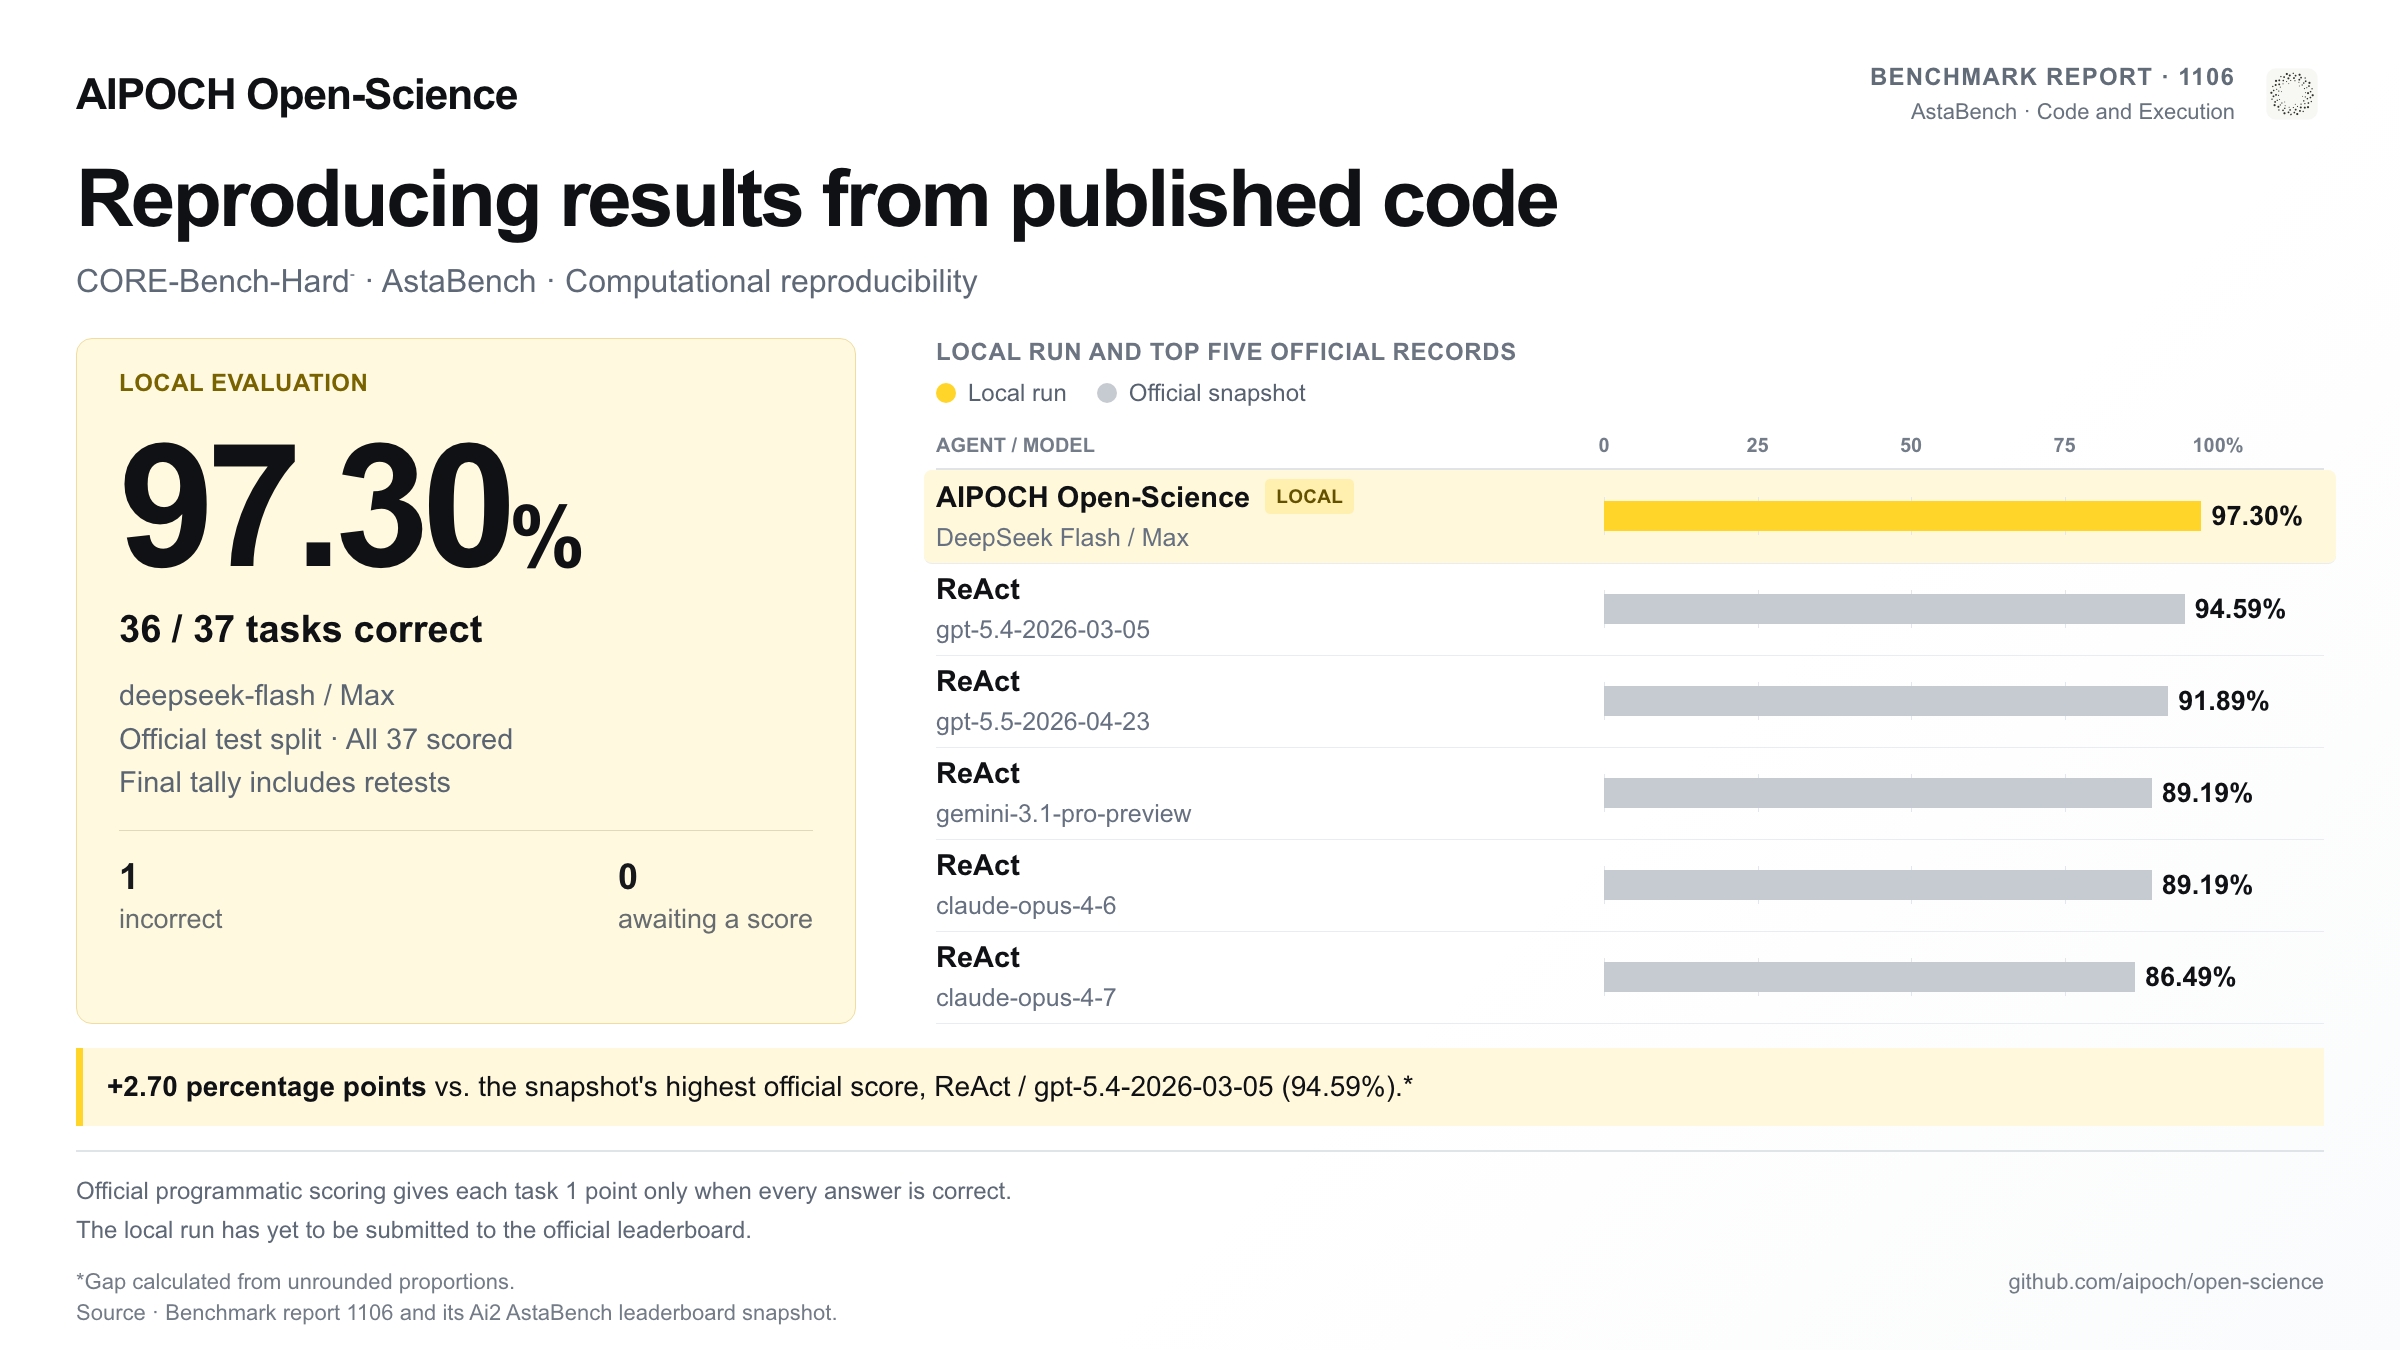
Figure 1. The reported local evaluation and five selected official records from the November 6 comparison snapshot. Yellow marks the local run; gray marks records listed as official in that snapshot. This is a comparison graphic, not an official leaderboard placement. View the full-size image.
Reading the November 6 leaderboard comparison
The comparison below uses an AIPOCH-reported local result, which has not been submitted to the AstaBench leaderboard. Individual run records were not available for independent inspection when this article was prepared, and comparability with published records remains to be established.
AIPOCH’s report lists 25 scored official records from the Ai2 AstaBench CORE-Bench-Hard test table. It orders them by accuracy and retains tied official ranks. The highest record in that dated report snapshot is 94.59% for ReAct with gpt-5.4-2026-03-05.
Against that snapshot, AIPOCH Open-Science’s local 36/37 result and the highest official record differ by approximately 2.70 percentage points, calculated from the unrounded proportions. The calculation compares scores on the same named test split, but the AIPOCH result was obtained locally and has not been accepted as an official leaderboard entry. That is an arithmetic gap between two reported figures, not a like-for-like performance comparison.
The official leaderboard is dynamic. Its current CORE-Bench-Hard records could not be independently confirmed during this review. The table below reproduces the November 6 reference records as given in AIPOCH’s supplied report; it must not be treated as a live ranking. The first row is the AIPOCH local result, labeled Local comparison; the remaining rows are official records from that snapshot.
| Rank in report snapshot | Agent | Submitter | Model | Accuracy | Record |
|---|---|---|---|---|---|
| — | AIPOCH Open-Science | Local | DeepSeek Flash / Max | 97.30% | Local comparison |
| 1 | ReAct | Ai2 | gpt-5.4-2026-03-05 | 94.59% | Official in snapshot |
| 2 | ReAct | Ai2 | gpt-5.5-2026-04-23 | 91.89% | Official in snapshot |
| 3 | ReAct | Ai2 | gemini-3.1-pro-preview | 89.19% | Official in snapshot |
| 3 | ReAct | Ai2 | claude-opus-4-6 | 89.19% | Official in snapshot |
| 5 | ReAct | Ai2 | claude-opus-4-7 | 86.49% | Official in snapshot |
| 6 | ReAct | Ai2 | claude-sonnet-4-6 | 72.97% | Official in snapshot |
| 7 | EvoScientist-Code | EvoScientist | GPT-5 (2025-08) | 66.67% | Official in snapshot |
| 8 | ReAct | Ai2 | o3 (2025-04) | 56.76% | Official in snapshot |
| 9 | Asta v0 | Ai2 | Claude Sonnet 4 (2025-05) (+ 6) | 48.65% | Official in snapshot |
| 10 | ReAct | Ai2 | GPT-5 (2025-08) | 45.95% | Official in snapshot |
| 10 | ReAct | Ai2 | GPT-5 Mini (2025-08) | 45.95% | Official in snapshot |
| 12 | ReAct | Ai2 | Claude Sonnet 4 (2025-05) | 40.54% | Official in snapshot |
| 13 | Smolagents Coder | Ai2 | Claude Sonnet 4 (2025-05) | 32.43% | Official in snapshot |
| 14 | Smolagents Coder | Ai2 | GPT-4.1 (2025-04) | 21.62% | Official in snapshot |
| 15 | ReAct | Ai2 | GPT-4.1 (2025-04) | 18.92% | Official in snapshot |
| 16 | Smolagents Coder | Ai2 | GPT-5 (2025-08) | 13.51% | Official in snapshot |
| 16 | Smolagents Coder | Ai2 | Gemini 2.5 Flash (2024-05) | 13.51% | Official in snapshot |
| 18 | ReAct | Ai2 | GPT-4o (2024-08) | 5.41% | Official in snapshot |
| 18 | Smolagents Coder | Ai2 | GPT-5 Mini (2025-08) | 5.41% | Official in snapshot |
| 18 | Smolagents Coder | Ai2 | GPT-4o (2024-08) | 5.41% | Official in snapshot |
| 21 | ReAct | Ai2 | Gemini 2.5 Flash (2024-05) | 2.70% | Official in snapshot |
| 22 | ReAct | Ai2 | Claude 3.5 Haiku (2024-10) | 0.00% | Official in snapshot |
| 22 | ReAct | Ai2 | Llama 4 Scout 17B (unpinned) | 0.00% | Official in snapshot |
| 22 | Smolagents Coder | Ai2 | Claude 3.5 Haiku (2024-10) | 0.00% | Official in snapshot |
| 22 | Smolagents Coder | Ai2 | Llama 4 Scout 17B (unpinned) | 0.00% | Official in snapshot |
The local result has no official rank. Equal scores share the same rank in the supplied snapshot, which is why ranks 3, 10, 16, 18, and 22 appear more than once.
What the 97.30% result shows
AIPOCH Open-Science scored 36 of 37 CORE-Bench-Hard test tasks correct in a local evaluation: 97.30% task accuracy on the official test split. All 37 tasks were scored by the official programmatic scorer, one was marked incorrect, and the final per-task tally includes retests.
The result describes one evaluation: one agent, one model configuration (DeepSeek Flash, Max reasoning), and 37 tasks from a single benchmark, run locally with the official python_session tool and scorer. It is reported here as a local evaluation; an official leaderboard rank follows submission and acceptance through AstaBench's process. The 94.59% reference and the 2.70-percentage-point gap both come from the November 6 snapshot attached to AIPOCH's report. A correct task score reflects the benchmark scorer's criteria; assessing the studies behind the tasks still calls for scientific judgment.
AIPOCH Open-Science keeps the inputs, generated outputs, environment details, and checks of such a run together in one project workspace, so a colleague can inspect the record and, where the environment allows, rerun it.