A research agent has to do more than suggest a plausible hypothesis. Given a research goal and a dataset, it must inspect the data, run an analysis, and explain how the evidence supports a testable finding. DiscoveryBench evaluates this multi-step process.
AIPOCH's supplied evaluation report records a mean final_score of 0.7467 for AIPOCH Open-Science on 25 selected DiscoveryBench validation tasks. It lists 18 full scores, two partial scores, and five zero scores. This is a local result for a selected task set, not an official leaderboard submission or rank.
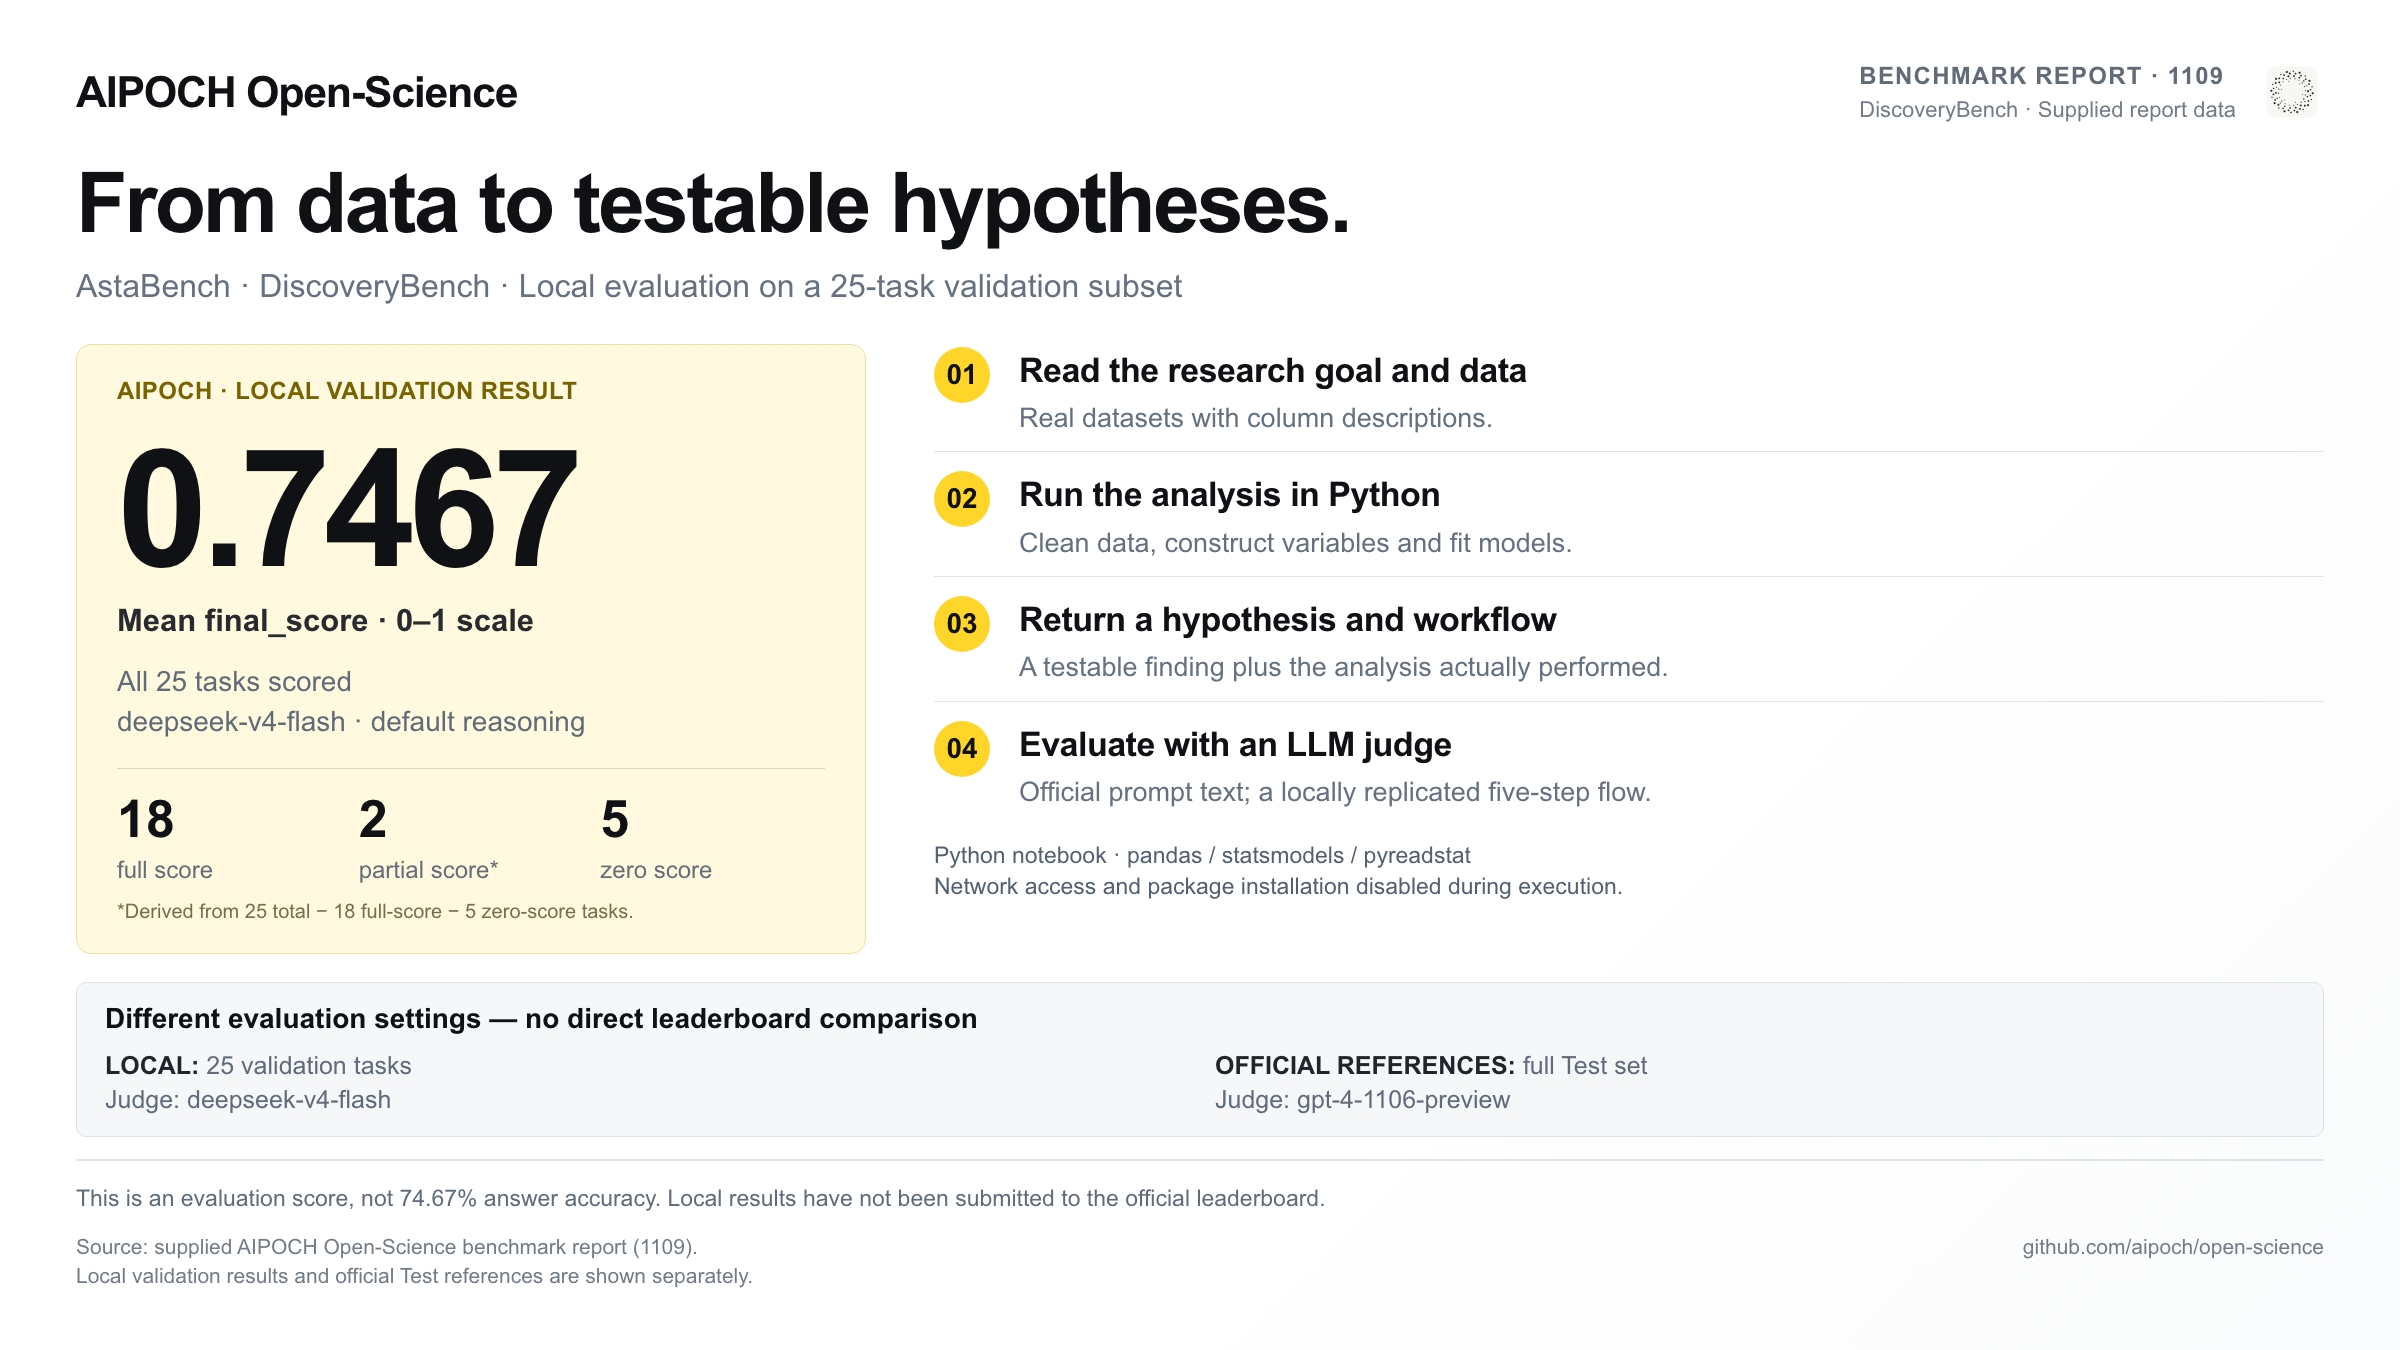
Figure 1. AIPOCH-reported local validation result and evaluation workflow. The image does not represent an official leaderboard placement.
Open-Science is designed to keep research work inspectable. A project can bring the question, files, analysis, outputs, and available execution evidence into one workspace. A .science package can carry selected conversation branches, file versions, Notebook records, and verification evidence for review or handoff. Importing a package does not rerun calculations or independently validate a conclusion.
What DiscoveryBench tests
DiscoveryBench gives an agent datasets, their descriptions, and a natural-language discovery goal. The agent must analyze the data and return a hypothesis alongside the workflow used to reach it. The benchmark paper describes this as multi-step, data-driven discovery across scientific domains.
The published evaluator code assesses aspects of the generated hypothesis and workflow, including context, variables, and relationships. Its final_score is a graded measure. A mean of 0.7467 does not mean that 74.67% of tasks were solved perfectly.
The reported AIPOCH Open-Science run
According to the supplied report, Open-Science ran 25 selected validation tasks in seven local batches. It used a DiscoveryBench-focused Specialist with seven analysis and error-handling skills, deepseek-v4-flash as the main model with default reasoning, and a local Python Notebook channel. Network access and package installation were disabled during execution.
The report says AIPOCH locally recreated the steps of DiscoveryBench's published evaluator and used deepseek-v4-flash as the judging model. Public task-level outputs and evaluator traces were not provided with this article, so the reported mean and the local judging implementation cannot yet be independently checked.
| Measure | AIPOCH-reported local result |
|---|---|
| Selected validation tasks scored | 25 |
Meanfinal_score | 0.7467 |
| Full-score tasks | 18 |
| Partial-score tasks | 2 (derived from the other reported counts) |
| Zero-score tasks | 5 |
Full comparison list supplied in the report
The table below preserves all 30 test records supplied in AIPOCH's report and shows the local Open-Science result separately. The report skips rank 3; no entry has been invented for that position. The listed test scores and ranks could not be independently confirmed against a fresh, complete official leaderboard extract.
The local and test rows are not directly comparable. AIPOCH used 25 selected validation tasks and a different judge. The other rows are presented in the report as full-test references. The local result has not been submitted to the official leaderboard.
| Rank in supplied report | Agent | Model listed in report | Score | Basis |
|---|---|---|---|---|
| — | AIPOCH Open-Science | deepseek-v4-flash | 0.7467 | Local; 25 validation tasks |
| 1 | ReAct | openai/gpt-5.5-2026-04-23 | 0.3893 | Test reference in report |
| 2 | ReAct | openai/gpt-5.4-2026-03-05 | 0.3776 | Test reference in report |
| 4 | ReAct | google/gemini-3.1-pro-preview | 0.3707 | Test reference in report |
| 5 | EvoScientist Coder | openrouter/moonshotai/kimi-k2.5 | 0.3433 | Test reference in report |
| 6 | ReAct | openai/o3-2025-04-16 | 0.3367 | Test reference in report |
| 7 | Asta v0 | Multiple models; report fieldmockllm/model | 0.3317 | Test reference in report |
| 8 | ReAct | anthropic/claude-opus-4-7 | 0.3281 | Test reference in report |
| 9 | ReAct | anthropic/claude-opus-4-6 | 0.3158 | Test reference in report |
| 10 | Asta DataVoyager | openai/o3 | 0.3113 | Test reference in report |
| 11 | ReAct | openai/gpt-4.1-2025-04-14 | 0.3054 | Test reference in report |
| 12 | ReAct | openai/gpt-5-2025-08-07 | 0.3048 | Test reference in report |
| 13 | ReAct | anthropic/claude-sonnet-4-6 | 0.2996 | Test reference in report |
| 14 | Asta DataVoyager | Multiple models; report fieldmockllm/model | 0.2988 | Test reference in report |
| 15 | Asta DataVoyager | openai/gpt-5 | 0.2956 | Test reference in report |
| 16 | Smolagents Coder | anthropic/claude-sonnet-4-20250514 | 0.2880 | Test reference in report |
| 17 | Smolagents Coder | openai/gpt-4.1-2025-04-14 | 0.2840 | Test reference in report |
| 18 | Smolagents Coder | openai/gpt-5-mini-2025-08-07 | 0.2768 | Test reference in report |
| 19 | Asta DataVoyager | openai/gpt-5 | 0.2704 | Test reference in report |
| 20 | ReAct | openai/gpt-5-mini-2025-08-07 | 0.2692 | Test reference in report |
| 21 | Smolagents Coder | openai/gpt-5-2025-08-07 | 0.2673 | Test reference in report |
| 22 | Asta DataVoyager | anthropic/claude-sonnet-4 | 0.2572 | Test reference in report |
| 23 | Smolagents Coder | google/gemini-2.5-flash-preview-05-20 | 0.2473 | Test reference in report |
| 24 | ReAct | anthropic/claude-3-5-haiku-20241022 | 0.2432 | Test reference in report |
| 25 | ReAct | anthropic/claude-sonnet-4-20250514 | 0.2322 | Test reference in report |
| 26 | Smolagents Coder | together/meta-llama/Llama-4-Scout-17B-16E-Instruct | 0.2016 | Test reference in report |
| 27 | Smolagents Coder | openai/gpt-4o-2024-08-06 | 0.1782 | Test reference in report |
| 28 | Smolagents Coder | anthropic/claude-3-5-haiku-20241022 | 0.1651 | Test reference in report |
| 29 | ReAct | openai/gpt-4o-2024-08-06 | 0.1323 | Test reference in report |
| 30 | ReAct | together/meta-llama/Llama-4-Scout-17B-16E-Instruct | 0.0586 | Test reference in report |
| 31 | ReAct | google/gemini-2.5-flash-preview-05-20 | 0.0193 | Test reference in report |
Rank 3 is absent from the supplied report. This is the full supplied comparison list, not a verified complete or current official ranking. Consult the official AstaBench leaderboard for current records.
How to interpret the result
The reported 0.7467 mean describes one Open-Science configuration on a selected local validation set. It does not establish an official placement or show that Open-Science outperformed the test records above. Differences in questions and judging prevent a direct ranking across those rows.
The task-level spread matters too: the report lists both full and zero scores. Public outputs would allow readers to inspect which hypotheses matched the reference, which analysis steps fell short, and whether repeated runs produce similar results.
Researchers can explore AIPOCH Open-Science, run an analysis on their own data, and inspect inputs, code, outputs, and available provenance before relying on a conclusion. A .science package can preserve selected work for a colleague's review, while scientific judgment and any independent rerun remain necessary.